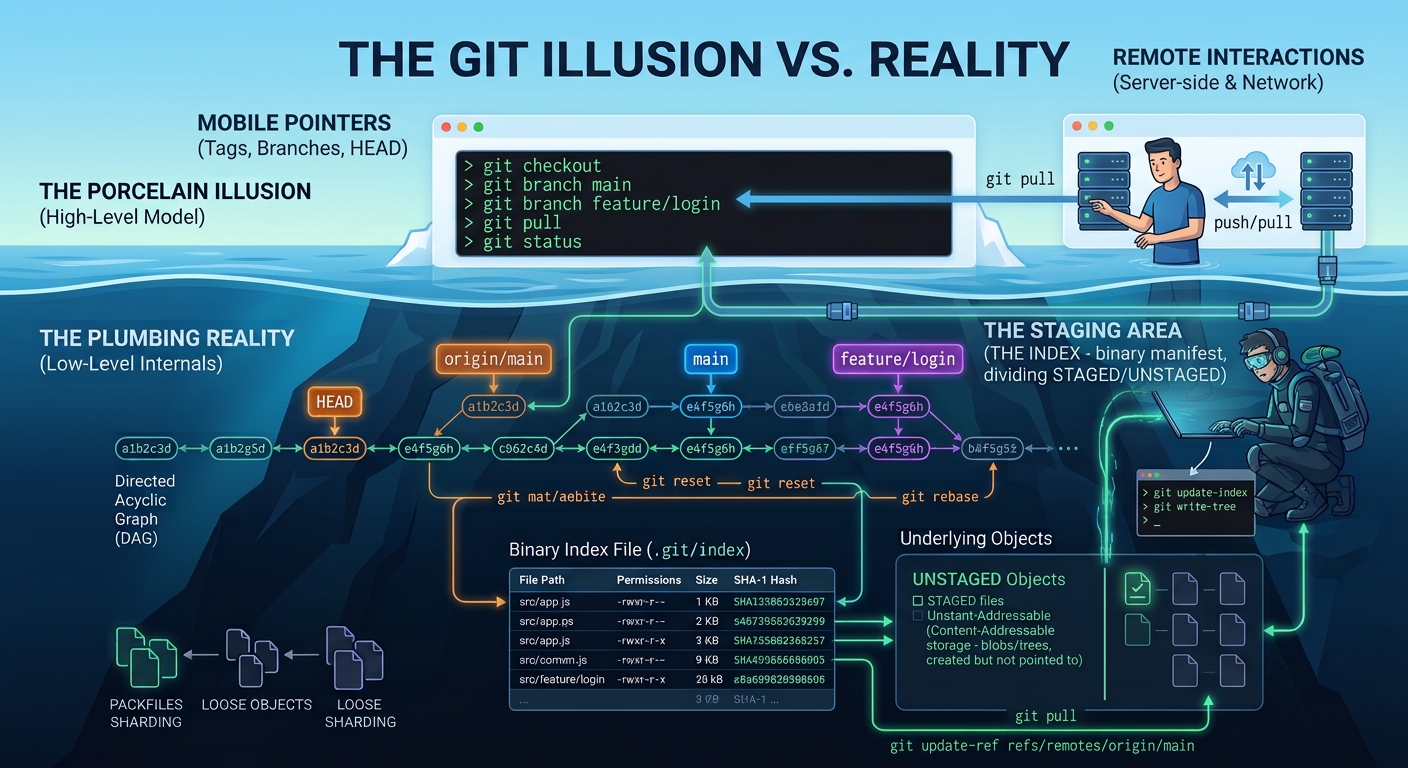
I've been having to switch a lot between git's high level and low level mental models the past few days. It's a bit jarring initially as you realise a lot of the things you rely on day to day aren't actually real. I wrote about that yesterday in my It's all an illusion post. It's not actually all that bad, but it does take a bit of getting used to. I put this cheatsheet together so I have something to refresh my memory next time I need to switch between the different models.
1. The Core Mental Model (The Chain of Commits)
At its absolute foundation, a Git repository is a web of history built from commits linked together in a Directed Acyclic Graph (DAG). Rather than a single straight chain, commits can branch out into parallel lines of development and merge back together. Every commit explicitly points backward to its parent commit(s), zero parents for a root commit, one for a standard commit, and two or more for a merge commit. Pretty much everything else in Git—branches, tags, remotes, and HEAD—does not store code or alter this fundamental graph. They are simply lightweight, mobile pointers that sit on top of specific commit nodes within this network.
2. Pointers & References (The Imaginary Layers)
Tags: Lightweight tags are literally just text files in
.git/refs/tags/containing a single 40-character commit hash. (Annotated tags add a tiny metadata object pointing to a commit).Branches (and Backup Branches): A branch is just a text file in
.git/refs/heads/containing a hash that points to a specific commit. When checked out, Git automatically updates this pointer to the newest commit created. Because it isn't a special entity, creating a "backup branch" is simply placing another pointer file on a specific commit node. This guarantees you can always navigate back to those commits by traversing backward through parent references in the acyclic graph.Remotes (Remote Tracking Branches): Files in
.git/refs/remotes/containing a hash pointing to the commit your local Git thinks a remote server's branch was pointing to the last time you communicated.HEAD: A single reference file (
.git/HEAD) pointing to the active branch file (or directly to a commit hash when detached). It tells Git where to attach the next commit.
3. Objects & Storage (The Underbelly)
At the lowest level, everything in Git falls into two distinct categories: files on disk inside .git/ (the plumbing implementation) and content-addressable objects (the logical data structures).
The Staging Area (The Index): Located at
.git/index, this is a single binary manifest file. Think of it like an embedded key-value database stored in a flat file—mapping file paths directly to blob hash keys alongside cached file system metadata.git addwrites file contents into the object store as blobs, then records their paths, hashes, and permissions into this index.The Object Store (
.git/objects/): This is just a flat directory on disk where Git stores all immutable core objects as individual files (compressed using zlib, named by their SHA-1 hash). Unlike the index, it is not a database file; it is simply a content-addressable storage folder containing four primary types of objects:Blobs: Raw file contents stored without names or paths. If two files anywhere in your repo have identical content, Git stores them only once.
Trees: Directory structures that map filenames and permissions to specific blob hashes or sub-trees.
Commits: Objects that bind a top-level root tree pointer, parent commit hashes, author metadata, and a commit message.
Tag Objects: Metadata wrappers (containing tagger info, date, and messages) that point explicitly to a commit object (as opposed to lightweight tags, which are just text pointer files).
4. Graph Operations & Commits
The 5 Components of a Commit: Every commit object is constructed from exactly 5 pieces of information:
| Component | Description |
|---|---|
| 1. Root Tree Pointer | Hash of the top-level directory snapshot. |
| 2. Parent Commit Hash(es) | Hash of preceding commit(s) (1 for standard, 2+ for merge, 0 for root). |
| 3. Author Info | Name, email, and original timestamp. |
| 4. Committer Info | Name, email, and timestamp of when the commit was applied. |
| 5. Commit Message | The text payload. |
Rebase as Copying: A rebase is an automated copy operation. It takes a sequence of commits and recreates their changes as brand-new commit objects with new hashes and updated committer timestamps (while retaining original author dates), chaining them onto your target destination commit.
Reset (git reset):
git resetis the primary operation you use when you want to "delete" or "undo" commits. However, technically it is purely pointer manipulation rather than actual deletion: all it does is make your active branch pointer point at a different commit in the acyclic graph commit history. Optionally, it leaves changes in your working directory and staging area (--soft,--mixed) or clears them out (--hard), leaving any unreferenced commits behind in the object store.
5. Connecting High-Level to Low-Level (Plumbing vs. Porcelain)
Porcelain vs. Plumbing Commands: High-level user commands (
git checkout,git commit,git merge) are called Porcelain. Low-level internal inspection/manipulation commands (git cat-file -p <hash>,git ls-tree,git update-ref) are called Plumbing. Looking at objects via plumbing reveals that the high-level commands are just convenience wrappers over reading/writing.git/pointer files and object hashes.Orphaned (Dangling) Commits & Reflog: When references move away (via
reset,rebase, or branch deletion), old commits remain in the object store. They become "dangling" or orphaned commits simply because they are no longer reachable by walking backward from any active branch or tag reference. The Reflog (.git/logs/) acts as a safety journal recording every past position ofHEADover the last 90 days, enabling recovery of any unreferenced node by repointing a reference back to it.Three-Way Merge Engine: A merge isn't a magical comparison between two branch tips. Git finds their Common Ancestor node in the DAG, generates diffs from
Ancestor → OursandAncestor → Theirs, combines those diffs, and creates a single Merge Commit with two parent hashes.
It can seem a bit daunting at first, but this is often the way with software when you look under the surface level because the way humans think about things often isn't the most optimum from a computer architecture perspective. The cool thing about git though is you can easily look underneath the surface level when you need or want to, and it's mostly all just text files so you can open them and see exactly where the various references point to.
In fact reading this cheatsheet and then dumping it into an LLM and then having a conversation about a particular situation you are in will likely lead to good results. You can paste output from commands you run, maybe even have the LLM generate commands for you. Then ask it to analyse the output, showing you which reference points to which commit. You can even get it to generate some ASCII art diagrams representing the situation at hand, that use actual real data from your command output. Be a bit careful, follow the logic through and ask questions because it doesn't always get things right. The LLM is just a probabilistic prediction machine trained on crazy amounts of data, so there are times when it starts getting things wrong, or it suddenly tells you the complete opposite of the thing it said just a few turns before. However it's normally possible to get to the answer to the problem you are looking for eventually.
 Just had to do quite the deep dive into git to figure out some issues I was having with my new